kv cache
2 articles
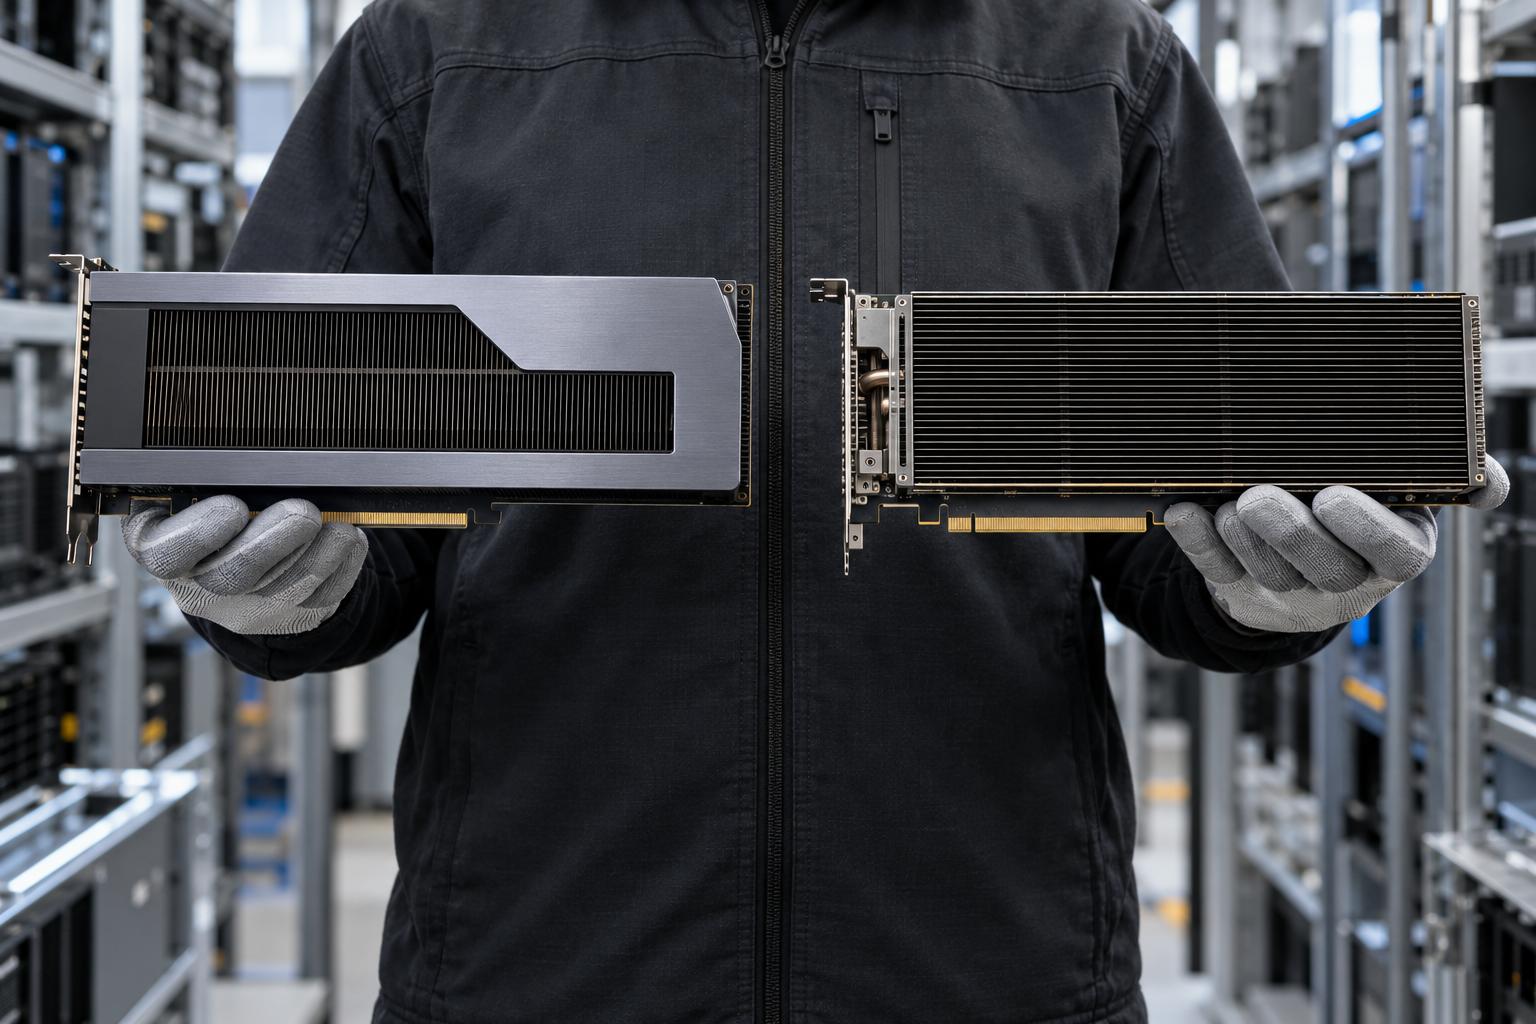
RTX PRO 6000 Server Edition vs L40S: Inference Cost
A 2026 comparison of RTX PRO 6000 Server Edition and L40S for private inference, covering 96 GB model fit, KV-cache budgets, matched latency benchmarks and three-year cost-per-token thresholds.
October 24, 2026• 21 min read
rtx pro 6000 server edition vs l40srtx pro 6000 blackwellnvidia l40s
Disaggregated Prefill/Decode Private Fleet Break-Even
A 2026 break-even model for private disaggregated prefill/decode fleets, covering SLO goodput, KV transfer, idle pool-hours, HBM opportunity cost, and conditional routing.
September 22, 2026• 22 min read
disaggregated prefill decodeprefill decode disaggregationllm inference