GPUSmith
Articles (English) - Page 4 / 5
What Is a Good GPU Utilization Percentage? The 80% Target
A 2026 data-driven guide to good GPU utilization percentages, covering NVIDIA's 80% SM Activity benchmark, Cast AI's 5% enterprise average, Model FLOPs Utilization, and how to monitor and raise GPU utilization.
Kimi K2 Hardware Requirements: VRAM, Nodes and Cost to Run
A 2026 guide to Kimi K2 hardware requirements covering VRAM and GPU needs, quantization tiers from 245GB to 1.09TB, Moonshot's 16-GPU node configuration, and self-hosting versus API cost.

Air-Gapped LLM Deployment: Running Frontier Models Offline
A 2026 analyst guide to air-gapped LLM deployment: DoD IL5/IL6 and FedRAMP frameworks, open-weight model licensing, GPU hardware costs from $30K H200s to $467K DGX clusters, and update pipelines.

DeepSeek R1 Self-Hosting Cost per Million Tokens (2026 Guide)
Analyzes DeepSeek R1 self-hosting costs per million tokens in 2026: GPU hardware requirements (8x H200 to 16x H100), benchmarked $0.11 to $16 per million token ranges, API pricing, and real deployment case studies.
SXM vs PCIe GPUs: Form Factor, Cooling and Use Cases
A 2026 comparison of SXM and PCIe NVIDIA GPUs covering HGX architecture, NVLink bandwidth, cooling requirements, H100 and A100 specs, cloud pricing, and real-world deployment case studies.

NVIDIA Nemotron 3 Ultra Hardware Requirements: VRAM and Cost
A 2026 analyst guide to NVIDIA Nemotron 3 Ultra hardware requirements: VRAM, minimum GPU counts for BF16 and NVFP4, DGX Spark and DGX Station paths, node configurations, and per-token self-hosting versus API costs.
InfiniBand vs Spectrum-X vs RoCE vs Ethernet for AI Clusters
A 2026 analyst comparison of InfiniBand, NVIDIA Spectrum-X, RoCEv2, and Ultra Ethernet for AI clusters, with Dell'Oro and 650 Group market data, latency benchmarks, and case studies from Meta, xAI, and Oracle.

400 VDC vs 800 VDC vs 415V AC: AI Datacenter Power Architecture
A 2026 comparison of 400 VDC, 800 VDC, and 415V AC data center power architectures, covering NVIDIA's monopolar Kyber design, OCP's bipolar Diablo 400 spec, copper and efficiency data, and rollout timelines.

How to Build an AI Datacenter: GPU Cluster Engineering Guide
A 2026 engineering guide to building an AI datacenter, covering GPU cluster architecture, InfiniBand vs Ethernet, power and cooling density, cost per megawatt, and grid interconnection bottlenecks.
NVIDIA AI Server OEM Comparison: Supermicro vs Dell vs HPE
2026 comparison of NVIDIA AI server OEMs: Dell, Supermicro, HPE, Lenovo, and Foxconn. Covers IDC market share, GB200/GB300 NVL72 racks, pricing, and 5 named deployments.
800 VDC Datacenter Power: Why AI Racks Are Going High-Voltage DC
An 2026 analyst breakdown of 800 VDC datacenter power architecture: why NVIDIA and OCP are moving AI racks to high-voltage DC, monopolar vs bipolar standards, costs, and safety gaps.

NVIDIA NVLink vs AMD Infinity Fabric: 2026 Interconnect Guide
Compares NVIDIA NVLink and AMD Infinity Fabric bandwidth, NVSwitch, UALink, and Ultra Ethernet in 2026, with GB200/GB300 NVL72 specs, MI300X data, and pricing.
Who Owns ZT Systems Now After the AMD-Sanmina Split?
Explains who owns ZT Systems as of 2026: AMD kept its design team while Sanmina bought its manufacturing plants for up to $3 billion, closing October 2025.
Is Kaytus on the Entity List? Inspur's Rebrand Explained
A 2026 analyst report tracing whether Kaytus and Aivres are on the US Entity List, their ownership by Entity Listed Inspur Group and IEIT Systems, the suspended BIS Affiliates Rule, and procurement compliance guidance for buyers.

NVIDIA Groq 3 LPU Explained: Vera Rubin Inference Chip
A 2026 technical explainer on the NVIDIA Groq 3 LPU: the $20 billion Groq licensing deal, Vera Rubin platform architecture, LP30 chip specs, and how LPUs compare to GPUs and TPUs.

Cerebras Wafer-Scale Engine: WSE-3 Architecture Explained (2026)
Deep dive into the Cerebras Wafer-Scale Engine WSE-3 architecture, CS-3 system specs, inference pricing, NVIDIA H100/B200 comparisons, and the May 2026 IPO, covering 2026 data.
NVIDIA vs AMD vs Intel vs Cerebras AI Accelerator Comparison
A 2026 analyst comparison of NVIDIA, AMD, Intel, and Cerebras AI accelerators covering architecture, MLPerf benchmarks, power efficiency, pricing, market share, and named deployments.
GLM-5.2 Hardware Requirements: VRAM, Nodes, and Costs
A 2026 guide to GLM-5.2 hardware requirements covering VRAM by quantization, minimum RAM, multi-GPU node sizing, self-hosting costs, and API pricing versus DeepSeek.
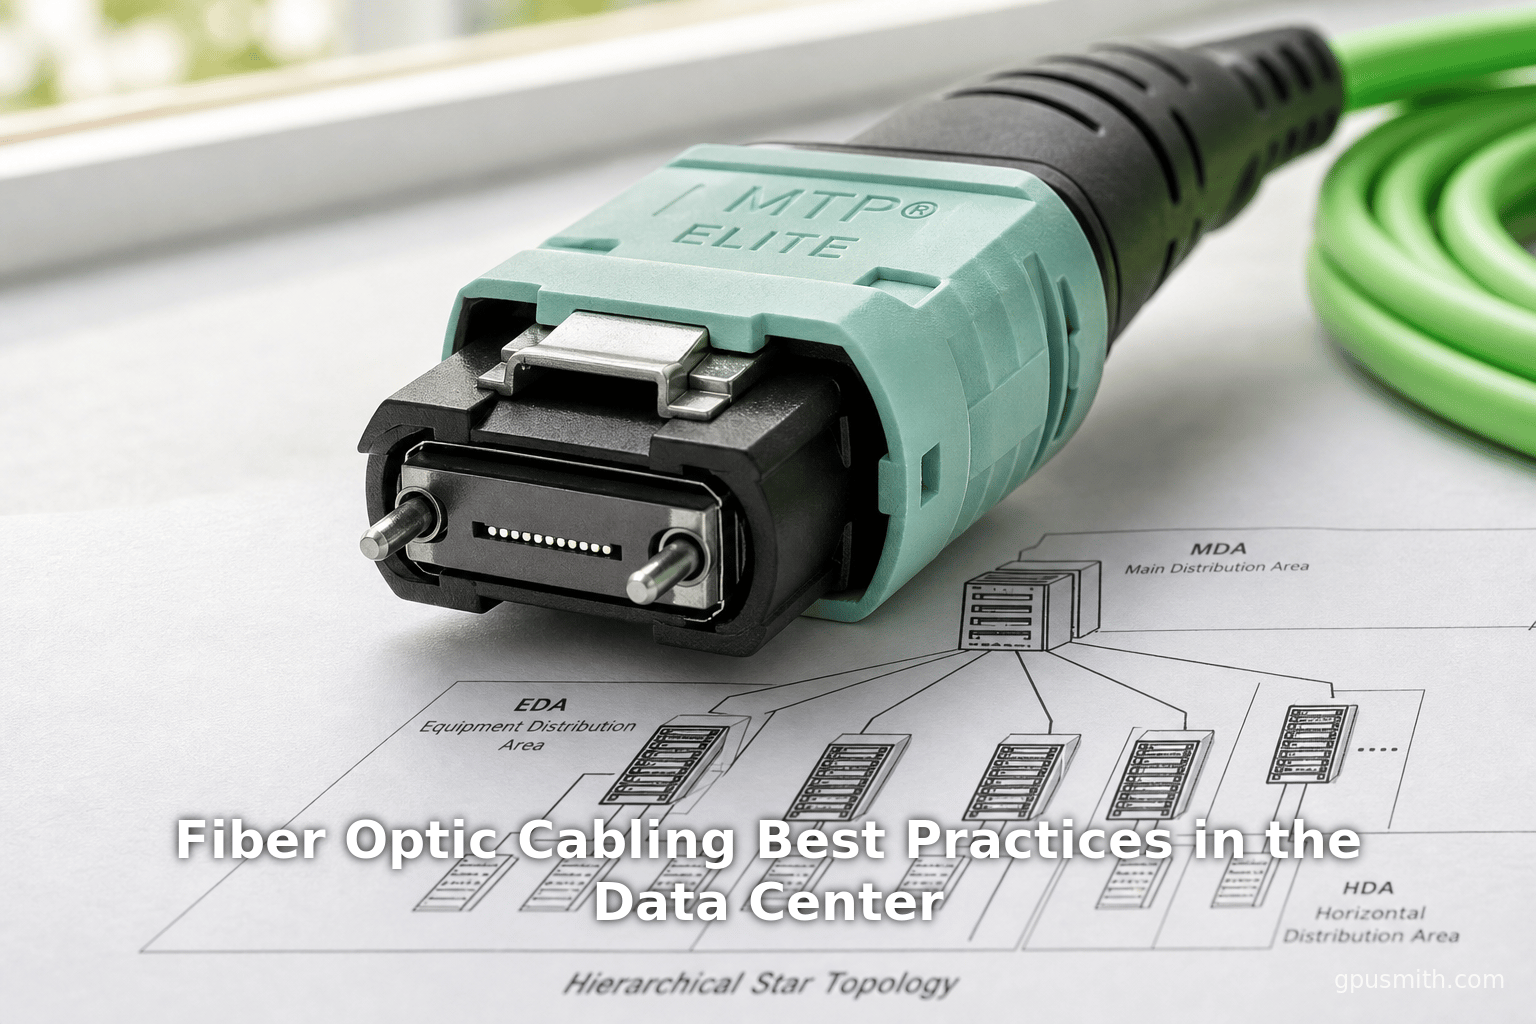
Fiber Optic Cabling Best Practices in the Data Center
A 2026 analyst guide to fiber optic cabling best practices in the data center, covering TIA-942, BICSI 002, MPO vs MTP connectors, MPO polarity methods A/B/C, and fiber loss budget calculations.
Hot Aisle vs Cold Aisle Containment for GPU Racks (2026)
Compares hot aisle vs cold aisle containment for data centers in 2026, with PUE data, GPU rack density thresholds up to 120 kW, liquid cooling market data, and 6 real-world case studies.
GPU Data Center Cooling Design: CRAC, CRAH and Liquid Cooling
A 2026 analyst guide to GPU data center cooling design covering CRAC vs CRAH, hot/cold aisle containment, direct-to-chip liquid cooling, chiller plants, and capacity calculation for AI racks.